What Is a Semantic Layer? A Guide for Teams Running AI Agents
One set of definitions between your data and everyone who queries it, people and agents alike. What it holds, what it isn't, and how to get one.
The short version
- A semantic layer is a set of business definitions (metrics, dimensions, entities, joins and access rules) written once and compiled into queries for every consumer.
- It sits between where data is stored and whoever asks questions of it: dashboards, notebooks, spreadsheets, applications and AI agents.
- It is not a warehouse, a BI tool or a data catalog, though BI tools often ship one inside them.
- For AI agents it replaces guessing: instead of writing SQL against raw tables, an agent asks for a defined metric and gets the governed answer.
The short definition
A semantic layer is a translation layer between the tables where your data lives and the people and programs that ask questions of it. It holds the meaning the tables don't: that "revenue" excludes refunds, that an "active customer" made a purchase in the last 30 days, that orders.user_id joins to users.id, and that the sales team may only see its own region.
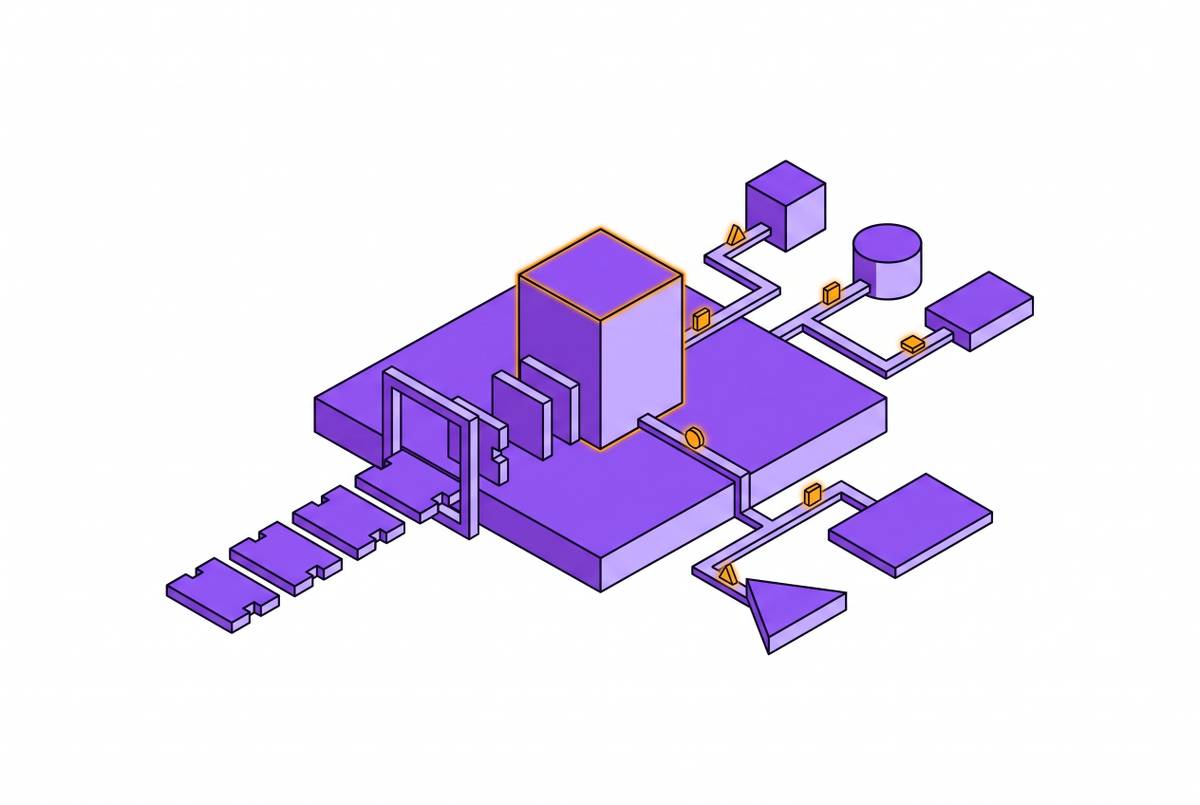
Those definitions are written once, usually as code or configuration kept in version control. When someone asks for "revenue by plan, last quarter", the layer looks up what revenue, plan and quarter mean, generates the SQL, applies the access rules, and returns the result. The person or agent asking never writes the join or the filter, so they can't write it differently from everyone else.
The problem it solves is old and familiar. Finance, product and the board deck each compute a headline number slightly differently, and every meeting starts by reconciling them. Our piece on why teams get different MRR answers walks through how that happens with a single metric.
What goes into a semantic layer
Products name these parts differently, but most semantic layers model the same handful of things:
- Entities and joins: the business objects (customer, subscription, order) and the keys that connect them, so a query that spans tables joins them the same way every time.
- Dimensions: the attributes you slice by, such as plan, country, signup cohort or channel, including time dimensions and the grains they roll up to (day, week, month, fiscal quarter).
- Measures and metrics: the aggregations (sum of amount, count of distinct users) and the metrics built on them, including filters, ratios and derived metrics like churn rate or net revenue retention.
- Access rules: who may see which rows and columns, for example region-scoped rows or masked personal data, enforced on every query rather than in each dashboard.
- Descriptions and ownership: plain-language definitions, an owner for each metric, and a status such as certified or experimental, so a reader (or a model) knows what a number means and whether to trust it.
Many layers add caching or pre-aggregation on top, so common queries are answered from precomputed results instead of scanning raw tables each time.
How a query flows through it
- A consumer asks for a metric by name, sliced by dimensions, over a time range: "MRR by plan, monthly, for 2026".
- The layer resolves each name to its definition: which table, which aggregation, which filters, which joins.
- It checks who is asking and applies their access rules.
- It generates SQL for the underlying engine (or serves a cached aggregate) and runs it.
- It returns the result with the metadata attached: the metric's description, owner and grain.
The consumer can be a dashboard, a spreadsheet connected over SQL, an internal app calling an API, or an AI agent calling a tool. Because all of them pass through the same definitions, they get the same number.
An example: defining MRR once
Here is what a metric definition can look like. The syntax below is illustrative rather than any one product's; every semantic layer has its own format, but the ingredients are the same.
entity: subscription
  table: billing.subscriptions
  primary_key: id
  joins:
    - customer: subscriptions.customer_id = customers.id

measure: recurring_amount
  expression: monthly_amount_cents / 100.0
  aggregation: sum

metric: mrr
  description: >
    Monthly recurring revenue from active, paid subscriptions.
    Annual plans are divided by 12. Excludes one-off charges,
    trials and refunds.
  measure: recurring_amount
  filters:
    - status = 'active'
    - is_trial = false
  time_dimension: billing_period_start
  owner: finance
status: certifiedThe decisions that usually drift between teams (do trials count, how annual plans are normalised, which date a subscription belongs to) are made once, in a file with an owner, and every consumer inherits them.
Semantic layer vs warehouse, metrics layer, BI and catalog
The term overlaps with several others. This is how they relate:
| Term | What it is | How it relates to a semantic layer |
|---|---|---|
| Data warehouse or database | Where the data is stored and queried (Postgres, a cloud warehouse, DuckDB over Parquet files). | The layer sits on top and generates the queries the engine runs. It stores definitions, not data. |
| Metrics layer | Definitions of metrics, often with their dimensions. | Usually used as a near-synonym. Where the two are distinguished, a metrics layer is the metric definitions alone and a semantic layer also covers entities, joins and access rules. |
| BI tool | Dashboards, charts and exploration for people. | Many BI tools have a semantic model built in, but it serves only that tool. A standalone ("headless") layer serves every consumer. |
| Data catalog | An inventory of datasets, columns, lineage and owners. | A catalog documents what exists; a semantic layer computes answers from it. They complement each other. |
| Text-to-SQL | A model that writes SQL from a question in plain language. | Without a layer, the model guesses joins and definitions from the schema. With one, it chooses among defined metrics instead. |
The "headless" idea, separating definitions from any one front end, is covered in Headless Analytics and the Case Against Monolithic BI Tools.
Why AI agents make it matter more
A human analyst who isn't sure what a column means can ask a colleague. An agent can't; it starts every task with whatever context it is handed. Point it at raw tables and it infers business logic from column names, and two agents (or the same agent on two days) can infer it differently. The result is the same forked truth as competing dashboards, only faster and harder to notice.
A semantic layer changes what the agent is allowed to do. Instead of writing arbitrary SQL, it picks a metric, the dimensions and a time range, and the layer does the rest. That narrows the room for error, keeps the agent's numbers identical to the dashboard's, and puts access rules in the data path instead of in a prompt.
- Bigger context windows don't solve this: pasting more schema in adds noise, not meaning. See Context Windows vs Pre-Modeled Datasets for Agent Accuracy.
- Exposing defined metrics as tools beats handing agents a raw SQL tool on accuracy and cost: MCP Tool Design for Metric Queries vs Raw Data Access.
- One layer serving analysts and agents alike: Designing a Shared Data Layer for Human and Agent Consumers.
- Keeping agent queries off the production database: Why AI Agents Must Never Touch Production Postgres.
Ways to get a semantic layer
Semantic layers come in a few shapes. The products named here are examples of each approach, not a ranking; check each vendor's own documentation for current pricing, supported databases and interfaces.
- Inside a BI tool. Looker's LookML is the best-known example: a modeling language that defines dimensions, measures and joins for everything built in Looker. Strong if one BI tool is where everyone works.
- Alongside your transformation code. The dbt Semantic Layer, powered by MetricFlow, keeps metric definitions in the same project as the dbt models that build your tables, and serves them to connected tools.
- Standalone (headless). Cube and AtScale sit between your data sources and any consumer, exposing the same definitions to BI tools, applications and other clients through their own interfaces.
- Pre-computed governed datasets for agents. Some platforms model metrics ahead of time into governed datasets and serve them to people and agents from one place. Dreambase, for example, does this for teams on Supabase: it pre-models data into governed Parquet datasets queried with DuckDB and exposes them through a single MCP server, so agents never touch the production database.
- Your own. A small team can start with metric definitions as SQL views plus a documented list of what each means. It works until the number of consumers and metrics grows past what people can keep in sync by hand.
How to evaluate one
Questions worth answering before you commit, roughly in order of how hard they are to change later:
- Where do definitions live? In files under version control with review, or in a UI? Can you see who changed a metric and when?
- What does it query? Does it support the database you run today (Postgres, a warehouse, files), and does it run analytics queries without loading your production database? See Analytics Separation of Concerns When Supabase Handles Both Transactional and Query Load.
- Who can consume it? List the interfaces it exposes (SQL, REST, GraphQL, MCP or native BI connectors) and check them against the tools and agents you actually use. API Surface Design as the Real Differentiator in Headless Analytics Backends goes into why this matters.
- How is access enforced? Row- and column-level rules applied in the layer on every query, per user or per agent, with an audit trail of what was asked. See Security Boundaries in MCP-Served Analytics Layers.
- How fast and how costly are queries? Is there caching or pre-aggregation, and what does a typical agent query cost to run?
- How portable are definitions? If you switch tools, can the definitions be exported, or do they have to be rewritten?
Getting started
- List the five to ten numbers people argue about most: usually revenue, MRR, active users, churn and conversion.
- For each, write the definition in plain language and name one owner who decides disputes.
- Model the entities and joins those metrics need, and nothing more yet.
- Move your main dashboards onto the layer first, and check that their numbers match what finance reports.
- Then give agents read-only access to the defined metrics, not to raw tables, and test them against a set of questions whose answers you already know.
- Add metrics as new questions come up, each with a description and an owner.
Frequently asked questions
Is a semantic layer the same as a metrics layer?
Mostly, and the terms are often used interchangeably. When people distinguish them, a metrics layer is the metric definitions alone, while a semantic layer also models entities, joins, dimensions and access rules.
Do I need a data warehouse to have a semantic layer?
Not always. Some semantic layers query Postgres or files directly. What matters is that analytics queries, and especially agent queries, don't run against the database your application depends on. Check which sources a given product supports in its documentation.
Does a semantic layer stop AI agents from hallucinating numbers?
It removes the most common cause: guessing what a metric means and how tables join. An agent that asks for a defined metric gets the governed answer. It can still misread a result or pick the wrong metric, so test agents against questions with known answers.
Where does MCP fit in?
The Model Context Protocol is one way to expose a semantic layer to agents: each defined metric or query becomes a tool the agent can call, with the layer's access rules applied behind it.
Are there open-source semantic layers?
Yes. Cube, for example, has an open-source core. Licences and which features are open change over time, so check each project's repository before you build on it.